Off-the-shelf Agents trigger on a per-task basis, meaning they run on each task as it reaches the Agent stage in a Workflow or when triggered by an Annotator in the Label Editor.
Configure and Use Off-the-Shelf Agents
Using an off-the-shelf Agent takes two steps: configure it once in the Agent catalog, then make it available where you need it. A single agent can be used in multiple Projects and Workflows, so you only need to configure it once.1
Configure the Agent in the Agent catalog
The Agent catalog is where you define what an Agent is and how Encord should reach it.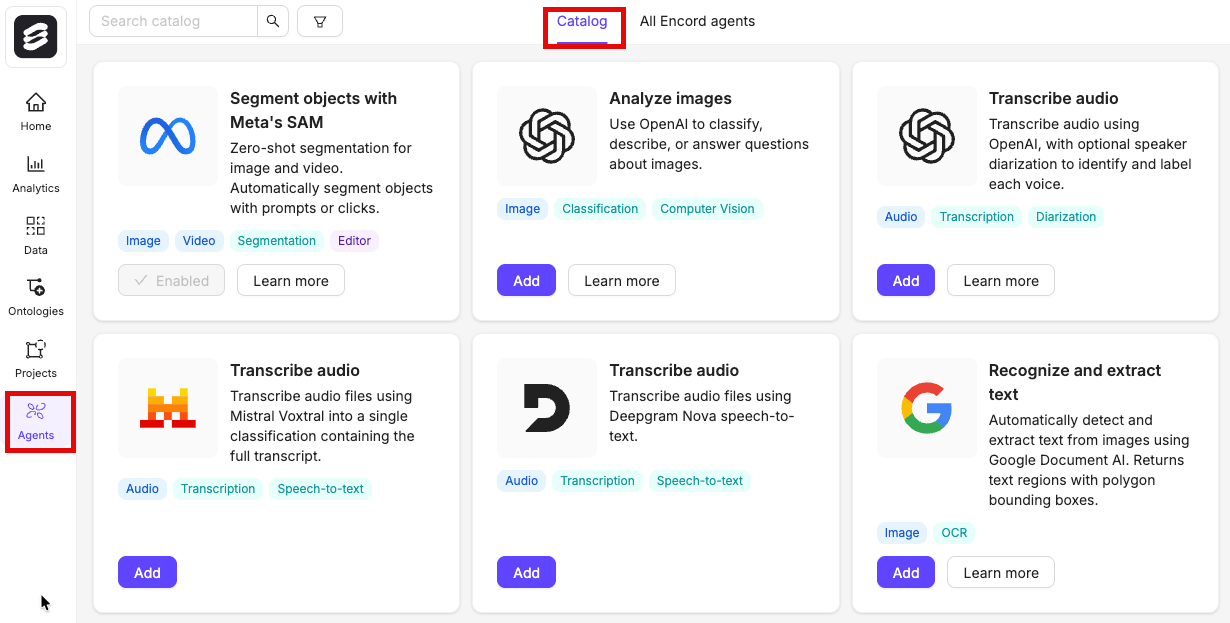
- Navigate to Agents in the left-hand navigation. The Agents catalog tab opens by default.
- Browse or search for agents, click Add to enable an agent.
- Give the Agent a meaningful name and description.
- Add Ontology and label target information, and any required external credentials if necessary.
- Add any additional configuration parameters required by the agent template.
- Click Add agent to save the configuration and enable the agent for use in your Projects. It is now listed in your list of agents.
Configuring an agent does not run it. The agent only processes tasks once you add it to a Project or Workflow.
2
Make the Agent available
Choose where the agent is used. Agents can be in a Workflow, in the Label Editor, or both.
In a Workflow
In a Workflow
Add an Agent stage to the Workflow and select the agent. All off-the-shelf Agents use the per-task trigger type, so the Agent runs on each task as it reaches the stage.
In the Label Editor
In the Label Editor
The Agent is automatically available to Annotators working in Projects that match the Ontology set up during configuration. They can then run the agent on demand from the Label Editor by right-clicking and selecting the agent.
External Credentials
Many agents require external credentials, such as OpenAI API keys or Google service accounts. You can add and manage these credentials in two ways:- While creating an agent: When you configure an off-the-shelf Agent, you can choose or create the required external credential directly in the form.
- From workspace settings: Go to Workspace settings > External credentials to create, reuse, or revoke credentials across agents.
Ontology & Label Targets
Many agents require you to specify an Ontology and Label Targets. These are the Ontology features that the Agent reads from or writes to.- Ontology - The Ontology the Agent uses.
- Label Targets - The specific classes within the Ontology that the Agent writes its output to. Only classes that the Agent template supports as outputs are available for selection.
The Agent can only be attached to Projects that use the Ontology specified. When creating an Agent directly from a Workflow stage, the Project’s Ontology is pre-filled automatically.
Repeatable Ontology Feature Requirements
Some agent templates declare one or more Ontology feature requirements as repeatable. A repeatable requirement lets you assign multiple Ontology features to a single role. For example, selecting several source object classes for an agent that merges or compares multiple class types simultaneously. When a requirement is repeatable, the agent configuration form displays a multi-select picker instead of the standard single-select dropdown. You can search and select as many eligible features as the template allows. Validation rules for repeatable requirements:- The template defines a minimum number of features you must select (default: 1). The form prevents submission until this minimum is met.
- If the template defines a maximum, the picker disables further selection once you reach that limit.
Source Object Classes: [ClassA] [ClassB] [ClassC]Ontology compatibility: When selecting an Ontology for an agent with repeatable requirements, Encord automatically excludes Ontologies that do not contain enough eligible features to satisfy the minimum selection count for each repeatable requirement.
List of Off-the-Shelf Agents
OpenAI Image Description
- What it does: Generates a detailed text description of an image using OpenAI vision models.
- Best for: Scene descriptions, captions, and summarizing what is happening in an image.
- Input data: Image data units.
- Output: A single text classification containing the description.
- Configuration:
- Credentials: Requires an OpenAI API key.
- Ontology requirements: A classification with a TEXT attribute where the image description is stored.
Claude Image Description
- What it does: Generates a detailed text description of an image using Anthropic Claude vision models.
- Best for: Image descriptions where you want to use Claude models.
- Input data: Image data units.
- Output: A single text classification containing the description.
- Configuration:
- Credentials: Requires an Anthropic API key.
- Ontology requirements: A classification with a TEXT attribute where the image description is stored.
Classify an Image (OpenAI)
- What it does: Classifies images into one or more ontology categories using OpenAI vision models.
- Best for: Category or label assignment, such as object presence, scene type, or attributes.
- Input data: Image data units.
- Output: A classification answer using your ontology options (single- or multi-select).
- Configuration:
- Credentials: Requires an OpenAI API key.
- Ontology requirements: A classification feature with options, using radio (single-select) or checklist (multi-select).
Ask a Question About an Image (OpenAI)
- What it does: Answers a natural-language question about an image (visual question answering).
- Best for: Targeted questions such as “What brands are visible?” or “What are the people doing?”
- Input data: Image data units.
- Output: A single text classification containing the answer.
- Configuration:
- Credentials: Requires an OpenAI API key.
- Ontology requirements: A classification with a TEXT attribute where the answer is stored.
Transcribe Audio
- What it does: Transcribes entire audio files using OpenAI Whisper into a single transcript.
- Best for: Full-file audio transcription (calls, interviews, long recordings) where you want one combined transcript.
- Input data: Audio data units.
- Output: A single text classification containing the full transcript.
- Configuration:
- Credentials: Requires an OpenAI API key.
- Ontology requirements: A classification with a TEXT attribute where the transcript is stored.
Diarize and Transcribe Audio
- What it does: Transcribes audio and performs two-speaker diarization, writing separate transcripts per speaker.
- Best for: Two-speaker conversations (for example, agent/customer) where you want per-speaker transcripts.
- Input data: Audio data units.
- Output:
- Time-based AUDIO objects for Speaker 1 and Speaker 2 segments.
- TEXT attributes on those objects with each speaker’s transcript.
- Configuration:
- Language: Optionally specify the language spoken in the audio. This can improve diarization and transcription quality; leave blank to auto-detect.
- Credentials: Requires an OpenAI API key.
- Ontology requirements:
- An AUDIO object for Speaker 1 segments, plus a TEXT attribute on that object.
- An AUDIO object for Speaker 2 segments, plus a TEXT attribute on that object.
Recognize and Extract Text
- What it does: Detects and extracts text from images using Google Document AI, returning polygon regions and associated text.
- Best for: OCR on documents, receipts, forms, and other scanned images where you need both text and its region.
- Input data: Image data units.
- Output:
- POLYGON objects for each detected text region.
- A TEXT attribute on each polygon containing the extracted text.
- Configuration:
- Credentials: Requires a Google Document AI service account.
- Ontology requirements:
- A POLYGON object type for OCR regions.
- A TEXT attribute attached to that polygon object for the extracted text.
CoreWeave Inference Agents
CoreWeave inference agents use open models hosted on CoreWeave Serverless Inference, served through Weights & Biases (W&B) Inference. The three image agents below can be run from the Label Editor or triggered in a Workflow. Supported input: Image data units in JPEG, PNG, GIF, or WebP format, up to 20 MiB per image. All three agents require your W&B API key, added as a CoreWeave external credential when configuring the agent. You can find your API key in your W&B account settings. You can also manage credentials in Workspace settings.The W&B API key is not the same as the CoreWeave Access Key ID and Secret Access Key used for a CoreWeave storage integration. Storage access keys do not work with these agents.
Requests run on your own W&B API key, so inference usage is billed to your W&B account and counts toward your W&B project’s concurrency limits.
- Open Agents and find the Analyze images with open models card in the Agents Catalog.
- Click Add, then choose Classify, Describe, or Answer questions.
- In the Add agent form, enter a Name and optionally a Description.
- Under API Key, select an existing W&B API key or enter a new one.
- Select an Ontology and compatible label targets under Ontology & label targets. See the requirements for your chosen agent below.
- Configure the model settings and any task-specific prompt or question, then click Add agent.
Shared Configuration
Describe an Image (CoreWeave)
- What it does: Generates a detailed text description of an image using the selected CoreWeave-hosted model.
- Best for: Scene descriptions, captions, and summaries of visible objects, people, actions, and text.
- Input data: Image data units.
- Output: A single text classification containing the description.
- Configuration: Uses the shared settings above, plus:
- Credentials: Requires a W&B API key registered as a CoreWeave external credential.
- Ontology requirements: A classification with a TEXT attribute where the image description is stored.
Classify an Image (CoreWeave)
- What it does: Classifies an image using the options in your Ontology and the selected CoreWeave-hosted model.
- Best for: Assigning categories such as scene type, object presence, or product condition.
- Input data: Image data units.
- Output: A classification answer using your Ontology options: one option for a radio classification, or zero or more options for a checklist classification.
- Configuration: Uses the shared settings above, plus:
- Credentials: Requires a W&B API key registered as a CoreWeave external credential.
- Ontology requirements: A classification feature with options, using radio (single-select) or checklist (multi-select).
Ask a Question About an Image (CoreWeave)
- What it does: Answers a natural-language question about an image using the selected CoreWeave-hosted model.
- Best for: Targeted questions about visible objects, brands, actions, or scene details.
- Input data: Image data units.
- Output: A single text classification containing the answer.
- Configuration: Uses the shared settings above, plus:
- Credentials: Requires a W&B API key registered as a CoreWeave external credential.
- Ontology requirements: A classification with a TEXT attribute where the answer is stored.